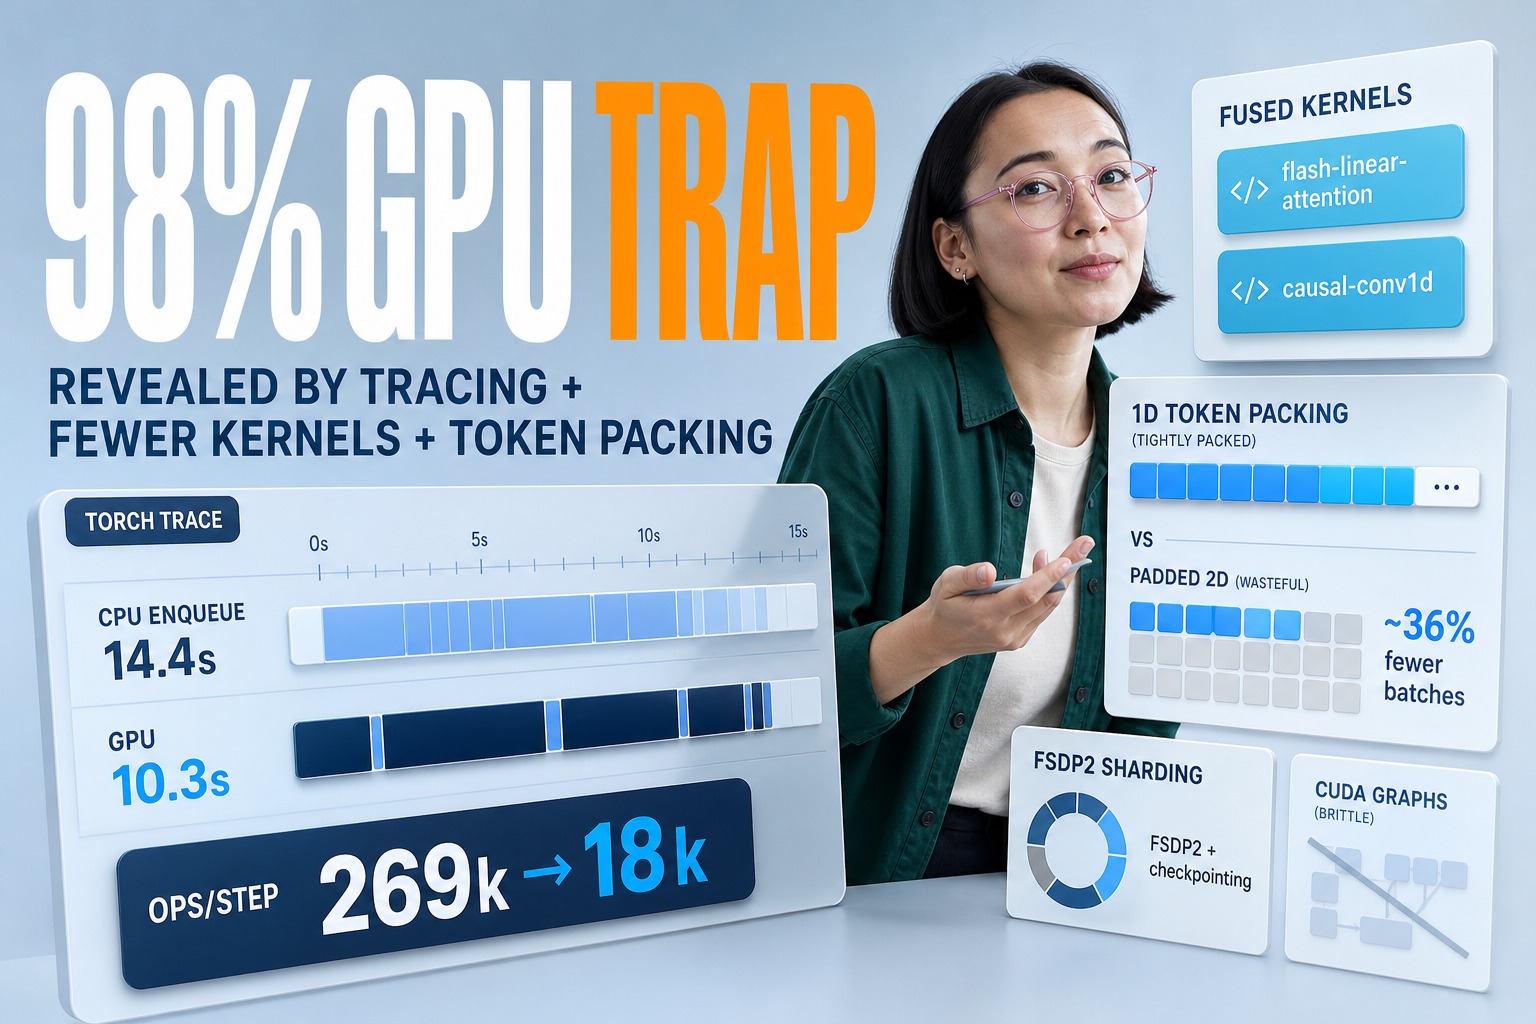
Why can fine-tuning still be slow if GPU utilization looks like 98%? → Because utilization only tells you the GPU was active, not that it was saturated; CPU enqueue time and kernel granularity can still stall the device.
What is the real engineering question teams should be searching for right now? → How to speed up LLM fine-tuning when GPU utilization is already high, without breaking training correctness.
What changed this week that makes this decision urgent? → A Qwen 3.8 27B fine-tune using transformers and torch FSDP2 was sped up by 6x even though baseline GPU utilization was already high, proving the bottleneck was above the GPU.
What is the non-obvious lever that drives most of the speedup? → Reducing the number of operations the CPU must enqueue, then eliminating padding waste by packing tokens more efficiently.
What should a CTO decide this quarter? → Whether to invest in system-level performance work (profiling, fused kernels, and input packing) rather than switching models or chasing a higher GPU utilization metric.
Quick Answer: how to speed up LLM fine-tuning when GPU utilization is already high
If your fine-tuning run shows 98% GPU utilization and still takes too long, treat that metric as a false comfort. The fastest path is to profile a single step with torch tracing, verify whether CPU step setup exceeds GPU execution time, then cut operation count via known fused kernels (for example flash-linear-attention and causal-conv1d for Qwen-style layers) and reduce padding waste by changing how you batch and pack tokens.
Our central claim at Plavno is simple and arguable: the biggest fine-tuning speedups happen above the GPU, at the orchestration boundary where the CPU schedules too many small kernels and your input pipeline wastes tokens; the right response is to optimize kernel topology and batching correctness before you touch model architecture.
The real bottleneck when GPU utilization is 98% is the CPU schedule, not the GPU
In the Qwen 3.8 27B fine-tuning setup we are grounding this article in, baseline training across a fixed dataset took 7 hours and 44 minutes at 9,396 tokens per second while the GPU reported 98% average utilization. Many teams would stop there and assume there is no headroom. In practice, that number only says the GPU was doing something most of the time; it says nothing about whether it was doing the right work, at the right granularity, with enough parallelism to be cost-effective.
The engineering smell is not the utilization number; it is the shape of the step. When CPU setup time per step is longer than GPU execution time per step, the GPU will stall waiting for work even though it registers as active. This is a scheduling and kernel-shape problem first, and it is why swapping clouds, changing instance types, or debating model families is often the wrong first decision.
- Look for CPU leading indicators: if the CPU is not running well ahead of the GPU, async launch is not saving you and the device will idle between bursts.
- Look for operation count explosion: hundreds of thousands of ops per step is a strong signal the CPU cannot enqueue fast enough.
- Look for padding waste: a rectangular token tensor forces padding to the batch maximum, silently converting GPU time into zeros.
- Look for fallback behavior: if your model silently falls back to unoptimized kernels, you can pay a large penalty without realizing it.
Why standard GPU utilization lies to you
Standard GPU utilization is time-based: it measures whether the device was doing anything, not whether it was doing enough. In the traced baseline step from the same workload, the CPU spent 14.4 seconds across 1,714,382 calls while the GPU spent 10.3 seconds across 269,448 operations. That is the opposite of what we want: in a healthy pipeline, the CPU queues work and the GPU stays busy, not the other way around.
Once we look at the step through that lens, the strategy changes. We stop trying to squeeze a few percent out of a kernel and start trying to remove entire categories of work that exist only because the model implementation and runtime are expressed as too many tiny operations.
A high utilization number can coexist with a stalled GPU if the CPU spends the step building and launching a mountain of micro-ops; the correct metric is whether CPU step setup stays well ahead of GPU execution over time.
Torch tracing is the fastest way to decide whether you have an enqueue stall
When teams ask us how to speed up LLM fine-tuning, we push them to answer a blunt question: is the bottleneck inside a few expensive GPU kernels, or is it the system above the kernels? Torch tracing gives you an actionable view because it surfaces both CPU and GPU timelines and aggregates where wall time is going. The key is not to trace an entire epoch; trace a small number of steps so the feedback loop is short.
In the Qwen run, tracing immediately revealed that the CPU side was doing too much work per step, and that the operation count was wildly high. That data justifies an optimization plan focused on reducing operations, not micro-optimizing math. It also prevents a common failure mode: spending weeks tuning batch size or mixed precision settings when the real limiter is CPU enqueue throughput.
Trace a representative step: run a short, step-limited trace so you can iterate quickly without waiting for a full training job.
Compare CPU total step time to GPU total step time: if CPU time is larger, you are likely starving the GPU with scheduling overhead.
Inspect call and op counts: very high counts imply kernel granularity problems and excessive Python or framework overhead.
Identify repeat offenders: if a small set of ops dominates counts or time, it is a candidate for a fused kernel or a different model implementation path.
Kernel count, not kernel speed, is the tuning knob most teams ignore
A multi-billion parameter model can produce a counterintuitive performance profile: the raw math is not what slows you down; the orchestration does. In the Qwen case, a batch matrix multiplication kernel appeared over 30,000 times in one step. That is a hint that the runtime is doing an enormous amount of repetitive kernel launches, and the CPU is paying per-launch overhead.
This is where many otherwise strong engineering teams make a costly mistake. They treat kernel fusion as an optional afterthought and focus on high-level training knobs. But when you have hundreds of thousands of GPU operations per step, the first-order win is to reduce the number of operations the CPU must enqueue, because the GPU cannot execute what it never gets scheduled.
If your trace shows hundreds of thousands of GPU operations per step, you do not have a GPU utilization problem; you have a kernel topology problem, and the fastest fix is fewer, larger kernels.
Why CUDA graphs are tempting and why FSDP2 makes them messy
CUDA graphs are conceptually perfect for this class of problem: record the kernels and replay them with a single CPU call, collapsing launch overhead. The catch, shown directly in the referenced Qwen optimization work, is that CUDA graphs come with limitations and conflict with the dynamism of FSDP2. If your sharding or execution path changes across steps, graph capture becomes fragile.
Torch.compile, which traces code and uses Triton to fuse kernels where possible, is also attractive. But for this LLM scenario, the optimization work concluded that there was little room left for torch.compile, and the bigger wins came from manually fused kernels that apply specialized fusion beyond what the compiler finds on its own.
- Manually fused kernels: use established community kernels such as flash-linear-attention and causal-conv1d when your model supports them, because they can replace many elementwise operations.
- Torch.compile with Triton: useful when fusion opportunities exist, but it may not move the needle for an LLM that already relies on specialized kernels.
- CUDA graphs: powerful for reducing CPU launch overhead, but brittle when execution is dynamic and can conflict with FSDP2.
- Flash Attention and similar kernels: can provide incremental gains, but the largest improvements can come from model-specific fused paths.
Manual fused kernels are the most reliable 3.7x win when your model supports them
In the measured Qwen 3.8 27B run, enabling the flash-linear-attention and causal-conv1d packages changed the economics of the entire step. End-to-end time dropped from 7 hours and 44 minutes to 2 hours and 5 minutes, a 3.7x improvement. The trace also made the mechanism visible: CPU calls fell to 118,316 and GPU operations fell to 18,060, which is a 15x reduction in executed operations.
This is why we argue the decision is architectural, not mystical. The GPU did not become faster; the system stopped asking it to do the same work through thousands of tiny fragments. In a distributed setup that already needed FSDP2 to fit weights and optimizer state, that kind of simplification has second-order benefits too: fewer synchronization points, fewer chances for small inefficiencies to cascade, and less sensitivity to CPU variability across nodes.
The trade-off is real: during training you need both forward and backward kernels, and some optimized kernels are forward-only because they were built for inference. That means kernel selection is not a generic shopping list; it is a compatibility decision tied to your model architecture and your training stack.
| Approach | What it optimizes | Trade-off you must accept |
|---|---|---|
| Manually fused kernels (flash-linear-attention, causal-conv1d) | Reduces operation count by fusing many small ops into fewer kernels | You must manage build and version compatibility, and ensure backward kernels exist for training |
| Torch.compile with Triton | Compiler-driven fusion and graph-level optimization | In some LLM workloads it may leave little room for additional gains beyond existing specialized kernels |
| CUDA graphs | Collapses CPU launch overhead by recording and replaying kernels | Limitations and conflicts with FSDP2 dynamism can make it impractical |
| Flash Attention-style kernels | Optimizes attention subgraphs | Can be a smaller gain if the dominant overhead is elsewhere, such as non-standard layers |
Convenience paths that silently fall back to unoptimized kernels are a production hazard: you can think you are running an optimized stack while paying baseline costs.
Treat kernels as build artifacts, or you will ship unpredictable performance
The optimization work we are grounding this in highlights a deployment trap: kernels often depend explicitly on the torch and CUDA versions installed, and if the exact match is not available the transformers model can silently fall back to an unoptimized kernel with low performance. That is not a research inconvenience; it is a production reliability problem. Your training throughput should not hinge on whether a runtime environment happened to resolve a precompiled wheel.
At Plavno, we treat performance-critical kernels the same way we treat any other production dependency: we pin versions, bake them into immutable images, and validate that the model actually uses the expected optimized path. If you are operating on a managed platform that bundles CUDA and flash attention in base environments and keeps profilers up to date, you still need verification, but it reduces the operational surface area.
When we help teams stabilize these environments through cloud software development, the goal is repeatable training performance across runs, not hero debugging when a cluster upgrade changes kernel resolution.
Lock torch and CUDA as a compatibility pair: decide the versions as a unit so kernel dependencies are stable.
Install kernels at image build time: avoid runtime installs that add startup time and variability.
Validate kernel selection in a trace: confirm the optimized kernels actually appear in the execution profile.
Fail loudly on fallback: treat silent fallback as an error condition in your job orchestration.
Padding is the hidden tax in 2D token batches, especially at large max tokens
After fused kernels, the next bottleneck in the Qwen run was not compute at all; it was wasted tokens. The baseline batching setup used 2D rectangular tensors with a maximum of 8,192 tokens per batch, padding each row to the maximum length within the batch. If your dataset has many shorter examples, padding becomes a direct tax: you pay for GPU work that produces no learning signal.
This is why we do not frame batching as a minor data engineering detail. For instruction tuning, where datasets can have a wide length distribution, padding waste can dominate. Even if you do not change the model or the GPU, improving packing can reduce the number of batches you must run, which reduces the number of optimizer steps and the entire wall-clock duration.
Why NestedTensor is not a free win once you pick exotic attention
If a model used only standard attention mechanisms, torch NestedTensor support can remove padding costs by eliminating rectangular padding altogether. But in the Qwen optimization path discussed, flash-linear-attention supports a more traditional 1D packed tensor approach, not NestedTensor. The moment you choose a fused attention kernel, you inherit its input constraints.
That constraint is not merely inconvenient; it shapes how you must reason about correctness. For fine-tuning, you cannot just pack tokens arbitrarily. You must ensure tokens in one example only attend to tokens within the same example, or you risk training on cross-example leakage.
- Keep 2D batching but sort by length: minimizes padding, but the ordering can introduce unexpected correlation in adjacent samples and bias training.
- Use NestedTensor for standard attention: removes padding overhead when compatible, but may be blocked by your chosen fused kernels.
- Use 1D packing: reduces padding substantially, but requires correctness work so attention stays within-example.
- Reduce max tokens per batch: can lower padding but may also reduce throughput if you become underfilled.
1D packing plus position identifiers is the difference between fast and wrong
The Qwen run achieved a second major speedup by switching from padded 2D batches to a 1D packed tensor approach compatible with flash-linear-attention. The critical detail is not the packing itself; it is the constraint needed for fine-tuning correctness. For pretraining, simply passing a packed tensor can be acceptable, but for fine-tuning you must ensure each example attends only to itself.
The stated approach was to compute the correct example position identifiers and pass them to the model, which then passes them to the fused attention kernels so the correct attention mask behavior emerges. With that change, training time dropped from 2 hours and 5 minutes to 1 hour and 17 minutes. The primary reason given was that packing increased the number of sequences per batch and reduced the total number of batches by approximately 36%, depending on the distribution and length of examples in the dataset.
There was also a secondary mechanism: the flash linear attention kernels require just-in-time compilation per input shape, and previously the shape was dynamic, leading to extra minutes of compilation. By stabilizing the shape through packing, compilation overhead fell. The trade-off is the one we care about as engineers: the input pipeline becomes more complex, and the probability of subtle bugs that affect model quality goes up.
If you change batching or packing, you have to treat it like a model change: validate that attention boundaries are correct, or you can buy speed by accidentally training on corrupted supervision.
A 6x speedup changes product planning because it changes iteration, not just cost
Taken together, the measured path went from 7 hours and 44 minutes to 1 hour and 17 minutes on a fixed dataset, while starting from an already-high utilization metric. That is a 6x speedup grounded in two moves: collapsing operation count with fused kernels and reducing wasted work with better packing. For a team trying to ship an assistant, a recommender, or a vertical fine-tuned model, this is not a vanity metric; it changes how quickly you can run experiments, debug failures, and converge on a usable behavior profile.
The practical implication is that training performance work belongs on the engineering roadmap, not as an after-hours optimization. When your run time drops by hours, you can afford more frequent evaluation checkpoints, more systematic ablations, and faster feedback from stakeholders. At Plavno we typically connect this kind of work to delivery outcomes through AI consulting, because speed is only valuable if it converts into better iteration discipline.
The moment fine-tuning drops from most of a workday to roughly an hour, the dominant risk shifts from compute cost to process quality: what you choose to test, measure, and approve each iteration.
How we evaluate fine-tuning performance at Plavno without chasing the wrong metric
We start with a simple principle: we do not accept GPU utilization as a performance proxy. We look at step composition under trace, we look for evidence that the CPU is enqueue-limited, and we treat operation count as a first-class metric because it is often the limiting factor in transformer implementations that have many small sub-ops.
From there we decide whether the first move is kernel-level or data-pipeline-level. If the trace shows an explosion of small operations and the model has known fused kernel paths, we prioritize those because they can collapse the step dramatically, as seen with flash-linear-attention and causal-conv1d. If the trace shows large padding waste at a high max token budget, we consider packing changes, but only when we can enforce correctness boundaries. These are the kinds of system decisions we embed in end-to-end delivery through our AI development company work, because shipping a fine-tuned model also requires a stable training substrate.
Prove where the time goes: require CPU and GPU traces for a representative step, not just utilization charts.
Reduce operation count before micro-tuning: if ops are in the hundreds of thousands, fusion is usually the biggest lever.
Verify training compatibility: confirm optimized kernels support forward and backward passes for your exact architecture.
Treat batching as correctness-sensitive: any packing change must preserve within-example attention boundaries.
Re-test after every environment change: kernel resolution and fallback behavior can change when torch or CUDA changes.
Where these optimizations matter most: instruction tuning pipelines and managed runtimes
The Qwen workload used the transformers library with an SFT dataset (HuggingFaceH4/ultrachat_200k) and relied on torch FSDP2 sharding to fit model weights and optimizer state on GPUs, with activation checkpointing to trade compute for memory and allow a larger per-GPU batch size. That combination is increasingly common in production fine-tuning because it lets teams work with large models without bespoke training frameworks.
In that environment, fused kernels and packing are multiplicative. FSDP2 and checkpointing make training feasible, but they also add complexity that makes naive approaches like CUDA graphs less practical. A managed runtime that bundles the latest CUDA and flash attention in base environments, tracks GPU utilization, temperature, and health, and keeps profilers up to date can reduce friction. But the engineering work still matters: you must choose kernels that match your model layers, and you must adopt batching strategies that do not harm training semantics.
When teams come to us to automate model updates or retraining as part of a product workflow, these performance choices become part of the system design, not a one-off tuning session. That is why we often connect them to AI automation initiatives where training runs are scheduled, monitored, and repeated.
- Rapid iteration on SFT datasets: shorter runs make it feasible to adjust prompts, formatting, and evaluation frequently without blocking a team.
- Large-model fine-tuning with sharding: when FSDP2 is required just to fit the model, reducing step overhead has outsized impact.
- Shared GPU clusters: fewer wasted operations reduces contention and makes scheduling more predictable across teams.
- Repeatable training jobs: baking kernels and pinning versions prevents silent regressions when environments change.
Risks teams underestimate: silent fallback, missing backward kernels, and quality drift
The most dangerous part of this optimization class is not writing a slower model; it is believing you wrote a faster one. Silent fallback to unoptimized kernels is explicitly called out as a risk, because kernel availability depends on exact torch and CUDA versions. If your environment is slightly off, you can lose the entire benefit while thinking the job is optimized.
The second risk is training completeness. Some kernels are forward-only because they were implemented to speed up inference. If you do not validate backward support, you can end up in a situation where training is impossible or forced onto mixed kernel paths that behave differently. The third risk comes from batching and packing changes: the input pipeline becomes more complex, and there is a high chance of introducing errors that impact model quality. Even length-sorting, which seems harmless, can introduce unexpected correlation in adjacent samples and bias the model.
At Plavno we argue that these risks are why performance optimization must be handled as a production engineering task with explicit validation gates, not as an ad hoc research tweak.
Operational guardrails we insist on before calling it a speedup
We require evidence that the optimized kernels are actually used, which means the trace must show the fused kernels replacing the prior elementwise operations. We also require a compatibility check across the full training path, not just a forward pass, because training needs both forward and backward kernels.
For batching and packing, we treat correctness as a first-order requirement. The mechanism described for 1D packing relies on passing example position identifiers so attention masking is correct. That implies you must have tests or evaluations that would catch cross-example attention leakage. Without that, you can reduce wall time and simultaneously degrade the model in a way that is hard to diagnose later.
Performance optimizations that touch kernels and batching should be gated by two proofs: the trace shows the intended kernel path, and evaluation confirms training behavior did not change in unintended ways.
The uncomfortable takeaway: model choice matters less than systems discipline
The sixfold improvement in this Qwen 3.8 27B fine-tune did not require a new model, a new dataset, or a higher utilization target; it required admitting that utilization is not the question and then engineering the runtime so the GPU is fed fewer, better-shaped operations and fewer padded tokens. That breaks a common practice in organizations: treating fine-tuning speed as a procurement issue instead of a systems issue.
If your fine-tuning runs look busy but move slowly, we can help you prove the bottleneck with tracing, stabilize your kernel and CUDA stack, and redesign batching so you gain speed without sacrificing correctness.
Author: Plavno team. Last updated: October 2026.
 Chat GPT
 Perplexity
 Claude
 Gemini

